
Common XML sitemap failures are less about writing XML than automatically including URLs you do not want in search results, overwriting lastmod with every build time, and considering the job done when Search Console says submitted. This guide includes URL quality and verification after submission.
The short answer
An XML sitemap lists canonical URLs you want searched; it is not a ranking switch
A sitemap supplies supporting information to help search engines discover pages, videos, images, and news and understand relationships and updates. It is especially useful for large or new sites, sites with weak internal links, and sites with many images, videos, or news items.
Listing a URL does not mean it will be crawled or indexed. Public canonical URLs that return 200, are not noindex, and should appear in search results belong in the sitemap. After submission, use Search Console and URL Inspection to check statuses separately.
Sites that benefit from an XML sitemap and those less dependent on one
Google can discover many URLs through normal crawling when important pages are reachable through internal links. A sitemap is therefore not essential for every site. If correctly generated and monitored, even a small site can use it to review URL structure and troubleshoot in Search Console.
Sites where discovery or update awareness is harder
- Many searchable product, job, article, or location URLs
- Recently launched with few external links
- Deep pages and weak internal linking
- Many images, videos, news items, or multilingual pages
- Frequent URL turnover from inventory or publication changes
Sites whose important URLs are easy to discover through normal crawling
- Around 500 or fewer searchable pages
- Important pages reachable from the home page through internal links
- Little information for image, video, or news search
- Few new URLs and stable publication
- The burden of managing incorrect CMS output exceeds the benefit
Check internal links as well as the sitemap
Important pages listed only in a sitemap are hard for users and search engines to discover. Make important URLs reachable through categories, related articles, breadcrumbs, and navigation; use the sitemap to supplement discovery.
Current XML sitemap specifications and limits
Each file has URL-count and size limits. Split larger sets into files and reference them from a sitemap index. The size limit applies before compression, not after.
| Item | Current specification | Practical check |
|---|---|---|
| Character encoding | UTF-8 | Ensure generator and HTTP-header encodings agree |
| URL format | Fully qualified absolute URL | /guide/ should not be used; use https://example.com/guide/ instead |
| Listed URLs | Canonical URLs you want in search results | Standardize HTTP/HTTPS, www, trailing slash, and case |
| Location | Anywhere on the site; the root is recommended | Without Search Console, coverage may be limited to the containing directory and below |
| Compression | gzip supported | The 50 MB limit applies uncompressed; avoid corrupt or double-compressed gzip |
| Sitemap index | Reference multiple sitemaps using loc | Referenced files are generally on the same site at the same level or below; avoid cycles |
| Namespace | http://www.sitemaps.org/schemas/sitemap/0.9 | The http namespace URI is correct; do not rewrite it as https |
Which URLs to include or exclude
A sitemap is not an inventory of every public URL. It is one signal of which canonical URLs you want in search results. Select URLs consistent with canonical, noindex, HTTP status, and internal links.
| URL state | List? | Reason and response |
|---|---|---|
| Canonical page returning 200 | Include | List the canonical URL you want in search results |
| 301 or 308 redirect | Exclude | List the final destination rather than the redirecting URL |
| 404, 410, or 5xx | Exclude | Remove deleted or inaccessible URLs from the generator |
| noindex page | Exclude | Avoid conflicting noindex and sitemap signals |
| A different canonical URL is specified | Generally exclude | For parameterized, duplicate, and print URLs, list only the canonical URL |
| Login, cart, checkout, and account pages | Exclude | Do not list user-specific pages unnecessary for public search |
| Internal search and filter URLs | Generally exclude | Avoid generating countless combinations or thin duplicates |
| Pagination | Decide by design | Consider listing pages with independent value and self-referencing canonicals |
| Canonical multilingual pages | Include | List each language's canonical URL and align hreflang |
| Staging and development | Exclude | Separate generators and environment variables to avoid contaminating production |
Align the signals
List canonical URLs intended for search results.
Make canonical URLs and indexability consistent on the page.
Link to important URLs and ensure they reliably return 200.
When all three align, search engines can better understand URL intent. Fix the generator first if a listed URL also has noindex, a different canonical, or a 301 redirect.
Create an XML sitemap in seven steps
A few dozen URLs can be maintained manually, but automated CMS or build generation is safer over time. Assign one owner and avoid conflicts between manual files and plugin output.
Identify the generator and ownership
Determine whether WordPress core, an SEO plugin, a static generator, a custom API, or a server batch produces the sitemap. Consolidate multiple generators into one owner.
List URLs intended for search
Build candidates from authoritative sources that know canonical URLs, such as routes, published CMS data, or a product database. Relying only on an external site crawl can miss orphaned URLs.
Define exclusions first
Define machine-checkable exclusions for drafts, private pages, noindex, redirects, deletions, duplicates, parameters, and authentication. Do not rely on manual review alone.
Generate XML or a sitemap index
Use UTF-8, absolute URLs, and the correct namespace. Split by content type or language as counts or uncompressed size grow, and reference the files from an index.
Set lastmod from a reliable source
Use meaningful change dates such as main content or product information updates. Do not update every URL for a deployment, cache regeneration, or footer-year change.
Validate the public URL and XML
Check that the sitemap returns HTTPS 200 and parses as XML, and that listed URLs return 200, match canonicals, and are indexable. Use automated tests as well as samples.
Submit and record results and changes
Announce the location in robots.txt and Search Console; record submission, last read, discovered URL count, errors, and generator version. Keep the previous file and rollback method.
Examples: XML, sitemap index, and robots.txt
The basic form is simple. If an XML URL contains &, escape it as & and use full rather than relative URLs.
A basic sitemap.xml
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://www.example.com/</loc>
    <lastmod>2026-07-29</lastmod>
  </url>
  <url>
    <loc>https://www.example.com/guide/</loc>
    <lastmod>2026-07-20T14:30:00+09:00</lastmod>
  </url>
</urlset>
lastmod is optional. If you cannot obtain the page's actual significant modification date, omit it rather than publishing an uncertain date.
A sitemap index for multiple files
<?xml version="1.0" encoding="UTF-8"?>
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <sitemap>
    <loc>https://www.example.com/sitemaps/pages.xml.gz</loc>
    <lastmod>2026-07-29</lastmod>
  </sitemap>
  <sitemap>
    <loc>https://www.example.com/sitemaps/articles.xml.gz</loc>
    <lastmod>2026-07-28</lastmod>
  </sitemap>
</sitemapindex>
The index's lastmod is the modification date of the referenced sitemap file itself, not each page.
Announce the location in robots.txt
User-agent: *
Disallow:

Sitemap: https://www.example.com/sitemap-index.xml
Sitemap: lines can appear more than once. Use an absolute sitemap URL and check that HTTP/HTTPS and www match the Search Console property.
Using lastmod, changefreq, and priority correctly
lastmod can help Google decide when to crawl known URLs, provided it consistently reflects reality. Artificially refreshing dates undermines trust in that information.
Significant content changed
Set the date when core content changes, such as additions or edits, product specifications or prices, structured data, or major links.
Only minor shared elements changed
Do not change the date for footer years, small navigation changes, CSS, ads, or cache regeneration when the main content's meaning is unchanged.
An accurate date is unavailable
For aggregations such as category and home pages where a meaningful update date is hard to determine, you need not force a lastmod value.
changefreq and priority are unnecessary for Google
Google does not use changefreq or priority. Prioritize canonical selection, accurate lastmod, internal links, HTTP responses, and Search Console monitoring instead. If another search engine or internal system needs them, check its specifications separately.
Generating sitemaps for WordPress, static sites, and online stores
The right approach depends on technology and publishing workflow. Generate from the system that knows publication status and canonical URLs, and do not manage the same URLs through multiple generators.
Choose core or an SEO plugin as the owner
A public WordPress site on version 5.5 or later normally provides /wp-sitemap.xml. If an SEO plugin generates /sitemap_index.xml or similar, compare included content, exclusions, and lastmod handling and choose one primary generator.
- Decide whether attachments, authors, tags, and custom post types belong
- Check for private, noindex, or redirecting URLs
- Check that caching or security settings do not block XML retrieval
Generate at build time from routes or a content registry
Use published routes, Markdown front matter, or published CMS API data to generate canonical URLs and update dates. This can control private and orphaned pages more reliably than an external crawl.
- Set the production domain via environment configuration; exclude localhost and preview URLs
- Use content update dates, not build times, for lastmod
- Check counts, XML syntax, duplicates, and HTTP responses in CI
Synchronize publication state with the database
Define handling of discontinued or out-of-stock products, closed jobs, and completed property sales. Temporary hiding versus permanent removal changes sitemap, status, and redirect policy.
- Split by product, category, article, and other types
- Do not regenerate deleted URLs from stale caches
- Alert on sudden daily increases or decreases in counts
Manage canonical URLs and hreflang in one registry
List each Japanese, English, Chinese, and other language page as its own canonical URL. If specifying hreflang in XML, include every language in the group and self-references, and avoid conflicts with HTML.
- Do not list translations before publication
- Do not point a language's canonical at another language
- Standardize language and region codes and URL design
Submit an XML sitemap to Google Search Console
Common ways to tell Google about a sitemap are Search Console and a robots.txt declaration. Use both with the same URL if you want to monitor operation.
Open the public URL directly
https://example.com/sitemap.xml or a sitemap index in a browser or curl and check that it returns 200 without login.
Choose the correct Search Console property
Check HTTP/HTTPS, www, and subdomains. With a URL-prefix property, submitting another URL version does not match the scope.
Submit through the Sitemaps report
Enter the sitemap or index path. For many files on a large site, usually submit the index.
Check last read, status, and discovered URLs
Beyond success, check last-read time, discovered page count, and child sitemap errors. Discovered URLs are not the same as indexed pages.
Add the same URL to robots.txt
As another discovery path, add a Sitemap: line. Multiple sitemaps can use multiple lines.
Why submit to Search Console?
Google may discover a sitemap through robots.txt, but the Search Console Sitemaps report shows only those submitted through the report or API. Submit there too to track errors and last read.
After submission, verify retrieval, URL quality, and indexing separately
A single pass/fail obscures causes. Check separately whether the file is readable, listed URLs are correct, and pages are eligible for indexing.
Check HTTPS, HTTP 200, XML response, robots.txt, authentication, CDN/WAF, and gzip.
Check absolute URLs, duplicates, canonical, noindex, redirects, 404s, and update dates.
Use page indexing reports and URL Inspection to check exclusion reasons and selected canonicals.
Basic server-side checks
# Check headers and status
curl -I https://www.example.com/sitemap.xml

# Check XML syntax where xmllint is available
curl -fsSL https://www.example.com/sitemap.xml | xmllint --noout -

# Check the final response including redirects
curl -IL https://www.example.com/sitemap.xml
Depending on the server, Content-Type may be application/xml or text/xml. Most important, search engines must retrieve well-formed XML without login rather than an HTML error page.
Inspect every URL or a sample
- Every loc is an absolute URL beginning with HTTPS
- HTTP, www, and trailing slashes match the canonical
- No duplicate URLs or unintended case variants
- No non-200 responses are listed
- No noindex, authentication, or robots blocking
- No canonical points to another URL
- lastmod is not a future or generation date
- URL count and uncompressed size are within limits
What to check in Search Console and official documentation
Interface wording and layout can change. Do not rely on screenshots alone; check your site's current responses and official documentation.
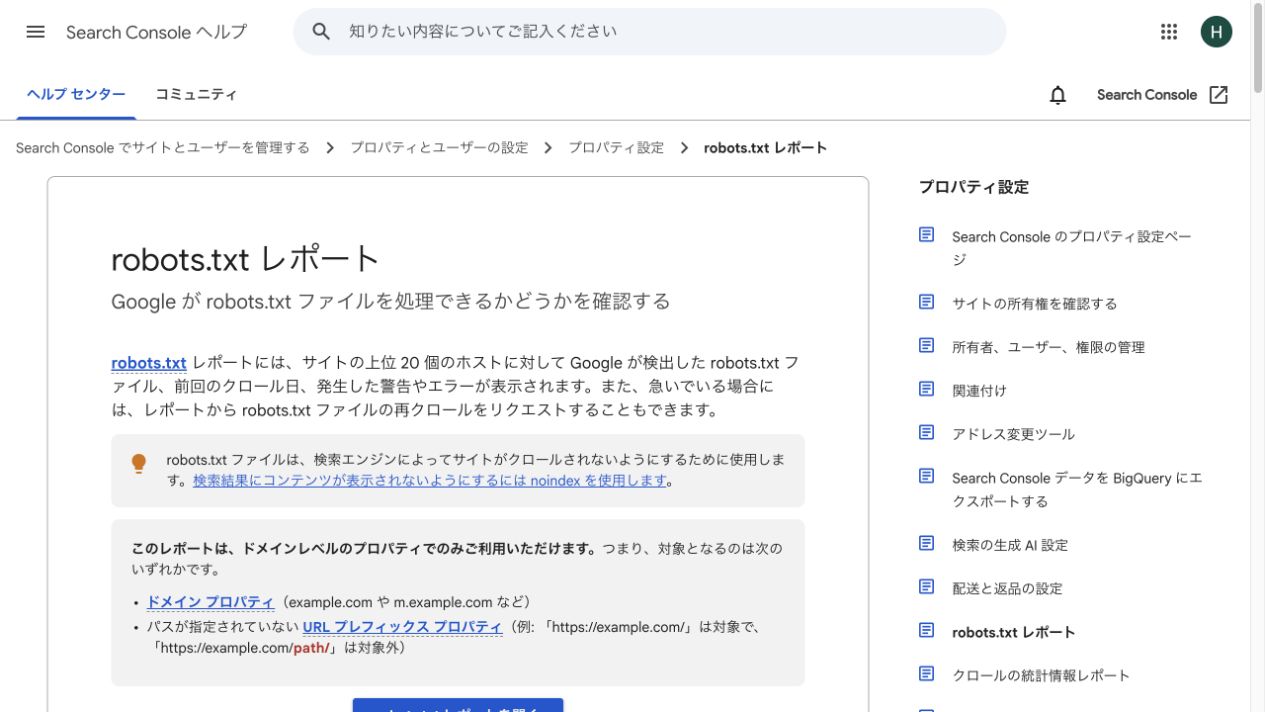
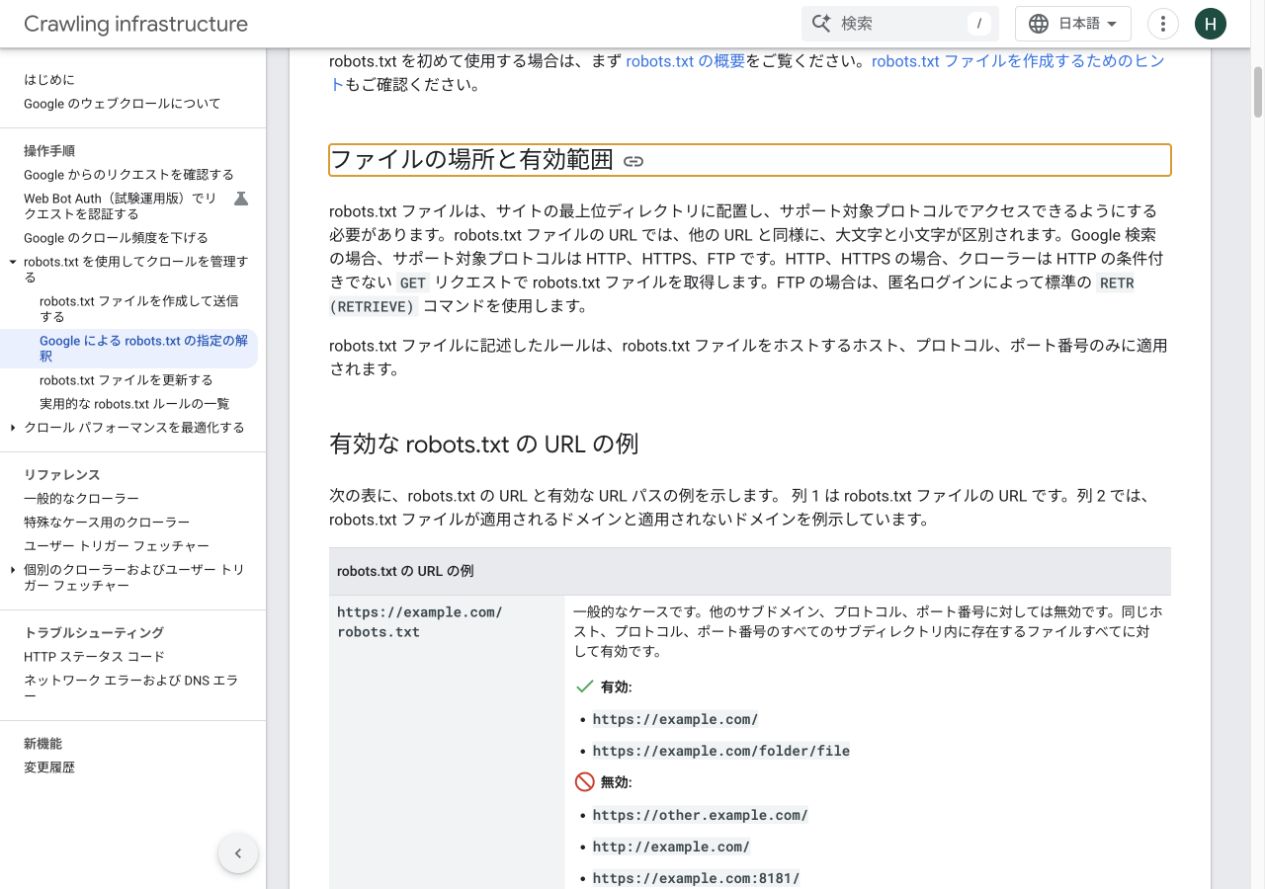
Troubleshooting XML sitemap errors such as couldn't fetch
A couldn't-fetch status in the Search Console report means Google has not retrieved the file itself. A sitemap-has-errors status instead means the file was retrieved but some URLs or XML elements could not be processed. First distinguish retrieval from parsing.
| Symptom | Main causes | Check and remedy |
|---|---|---|
| Couldn't fetch | robots.txt blocking, 404, server outages, WAF/CDN, manual actions, low crawl demand, and other causes | Open the URL directly and check crawl permission and page retrieval with URL Inspection's live test. Fix the cause and resubmit |
| 404 Not Found | Mistyped submitted URL, stopped generation, permalink or routing changes | Open the exact URL submitted to Search Console and check the generator and rewrite settings |
| 403 or authentication screen | Basic authentication, IP limits, bot protection, or security plugins | Check that Googlebot can access both sitemap and listed URLs, and configure necessary allow rules |
| 5xx or timeout | Expensive dynamic generation, database failures, cache misses, or huge files | Consider static caching, splitting, or asynchronous generation; inspect server logs for Googlebot responses |
| HTML is returned | Internal forwarding to a 404 or login page, cache misconfiguration, or application fallback | Inspect the response body as well as Content-Type and prioritize the XML route over catch-all routes |
| XML cannot be parsed | Missing closing tags, invalid characters, missing escapes, BOM, or encoding problems | Parse with an XML validator or xmllint and correctly escape ampersands and other URL characters |
| URL not allowed | Another domain, HTTP/HTTPS or www mismatch, or a directory above or beside the sitemap | Check absolute URLs and location scope. If needed, put it at the root or satisfy Search Console's cross-site submission conditions |
| URL cannot be followed | Relative URLs, redirect chains, JavaScript redirects, or meta refresh | List the final canonical absolute URL directly |
| File-size or URL-count limit exceeded | More than 50 MB or 50,000 URLs | Split by page type, language, or update frequency and reference files from an index |
| Date format error | Non-W3C Datetime format, missing time zone, or future date | YYYY-MM-DD or a date-time with time zone; fix the source data |
| Discovered URLs drop sharply | Publication flag or filter changes, generation failure, or missing child sitemap | Compare the previous file, counts, generation logs, and index references |
| Success but not indexed | Duplicates, insufficient quality, crawled but not indexed, noindex, soft 404, or a different selected canonical | Inspect individual reasons in the page indexing report and URL Inspection; fix causes beyond the sitemap |
Order for fixing errors
Retrieve the same URL externally
Check in a private window, curl, and external monitoring, not only an administrator's logged-in browser. Avoid relying on authentication cookies.
Compare server logs with Search Console details
Check Googlebot times, status, latency, and CDN/WAF denial records rather than guessing from the interface.
Fix XML syntax and listed URLs separately
First resolve problems retrieving the file, then address individual redirects, noindex, and canonical mismatches.
Resubmit after fixing and monitor for several days
Google retries retrieval failures for a while, but stops if failures continue. After fixing the cause, submit a new request and record last read and errors.
Extended sitemaps for images, video, news, and multilingual sites
Image, video, news, and hreflang namespaces can extend ordinary URL information, and multiple extensions can be combined for one URL. They increase file size, so use them when content and operational purpose justify them.
Help discover image URLs
Supplement discovery of images that normal crawling may miss, such as JavaScript-loaded or CDN images. Check current required fields in official documentation and remove deprecated tags.
Provide video metadata
Add thumbnail, title, description, and playback page. Check whether video is the page's main content and whether Googlebot can retrieve the video and thumbnail.
Manage articles published within two days
A news sitemap generally includes only articles from the last two days and at most 1,000 news entries per file. Ordinary web-search URLs can remain in a separate regular sitemap.
Associate language- and region-specific URLs
Each URL's language variants can be declared using xhtml:link. As with HTML hreflang, align reciprocal references, self-references, and canonical URLs.
XML sitemap checklist before publishing and after updates
A sitemap is not a one-time task. Revalidate after CMS updates, URL changes, domain migrations, language additions, or bulk deletions. Add these checks to release procedures or CI to reduce oversight.
File and generator
- One generator owns the output and does not duplicate it
- Parses as well-formed UTF-8 XML
- The public HTTPS URL returns 200
- Authentication, robots.txt, and WAF do not prevent retrieval
- At most 50,000 URLs and 50 MB uncompressed
- Split with an index when limits are exceeded
- gzip files decompress successfully
- No non-production domains are included
Listed URL quality
- loc values are fully qualified absolute URLs
- HTTP/HTTPS, www, and trailing slash match the canonical
- No non-200 URLs are listed
- No noindex or authentication-required URLs
- Exclude internal search, carts, and parameter duplicates
- Deleted or merged URLs are not regenerated
- Important URLs are also reachable through internal links
- Multilingual URLs and hreflang groups agree
Update dates and post-submission monitoring
- lastmod represents a real significant update
- Build time does not update every URL
- Omit lastmod where no reliable date exists
- robots.txt and Search Console use the same sitemap URL
- Record Search Console's last-read time
- Monitor sudden changes in discovered URL counts
- Check page indexing in a separate report
- Save the previous file and rollback procedure
Official sources reviewed
Specifications can change with search engines and CMSs. We checked the following primary sources on July 29, 2026.
- Google Search Central: Learn about sitemapsPurpose, sites that need them, the approximately 500-page guideline, and the absence of crawling or indexing guarantees
- Google Search Central: Build and submit a sitemap50,000 URLs and 50 MB, UTF-8, absolute URLs, canonical, generation, and submission
- Google Search Central: Sitemap indexesSplitting large sites, 50,000 loc entries, and Search Console submission limits
- Google Search Console Help: Sitemaps reportSuccess, fetch failures, parsing errors, retries, discovered URLs, and troubleshooting
- Google Search Central Blog: Ping retirement and lastmodPing endpoint retirement, accurate lastmod, and changefreq and priority
- Google Search Central: Combining sitemap extensionsImage, video, news, and hreflang namespaces and combined use
- Google Search Central: Image sitemapsCurrent requirements for image URLs and deprecated tags
- Google Search Central: News sitemapsThe past two days, 1,000 entries per file, and required elements
- WordPress Developer Resources: WP_SitemapsWordPress core sitemap features, routing, and robots.txt integration
XML sitemap FAQ
Will submitting an XML sitemap get every page indexed by Google?
No. A sitemap is a hint that helps discovery and crawling; it does not guarantee crawling, indexing, or rankings. Also check page quality, canonical, noindex, internal links, and duplicates.
Does a small site need an XML sitemap?
It may not be essential if important pages are internally linked from the home page, around 500 or fewer pages are searchable, and the site has little image, video, or news content. Correct automatic CMS generation can still help review URL structure and monitor Search Console.
Does updating lastmod daily help SEO?
No. Record the accurate date of significant changes to main content, structured data, or major links. Changing every date daily or on every deployment undermines lastmod's reliability. Omit it where no reliable date exists.
Should I set changefreq or priority?
Google does not use them. For Google, prioritize canonical URLs, accurate lastmod, internal links, retrieval, and Search Console verification.
Does a robots.txt Sitemap line make Search Console submission unnecessary?
robots.txt can announce the location to Google. Search Console submission also shows last read, status, discovered URLs, and parsing errors, so using both is a clear operational approach.
What is the difference between sitemap.xml and sitemap_index.xml?
A sitemap.xml file directly lists page URLs. A sitemap index groups multiple sitemaps, useful when count or file-size limits are exceeded or when splitting by article, product, or language.
Can noindex pages be included in an XML sitemap?
Generally exclude them because noindex conflicts with a sitemap's signal that URLs should appear in search. Also exclude redirects, 404s, duplicates, and login-required pages.
Does removing a sitemap from Search Console remove its URLs from search results?
No. Removing the submitted entry from the report does not automatically remove URLs Google already knows or has indexed. To make URLs nonpublic, separately consider HTTP status, noindex, removal tools, or another method appropriate to the goal.
URL quality and verification matter beyond creating the XML sitemap
An XML sitemap tells search engines which canonical URLs you want in search and supports discovery and crawling. Respect the 50,000-URL and 50 MB uncompressed limits and list canonical URLs returning 200. Use real significant update dates for lastmod; do not spend effort on changefreq, priority, or retired ping submissions for Google.
After publishing, check file retrieval, XML parsing, URL quality, Search Console reading, and page indexing separately. Incorporate the workflow into your CMS, CI, and procedures for reproducible operation as the site or team changes.
Finite Field editorial update policyWe prioritize official search-engine and CMS materials and distinguish specifications, general recommendations, and site-specific decisions. We review interface and specification changes and revise the article when URLs, update dates, or verification procedures are affected.